Azure Architects Using Dapr in Container Apps: What to Add Before Going to Production
The pilot went live on a Tuesday. Three container apps, Dapr pub/sub for order events, Dapr state for a small checkout service, all running in a single Azure Container Apps environment. Nobody touched the design after the demo.
Two weeks later, someone pushed a new revision of the fulfillment worker at 11:40 on a busy morning. Traffic shifted, the old replicas were shut down, and a handful of orders that the worker had already acknowledged, but was still processing in memory, simply stopped. No errors in the dashboard, just customers asking where their confirmation emails went. The same week, a security review flagged a Dapr component YAML in the repo with a full Service Bus connection string pasted into its metadata.
Neither problem was caused by Dapr or by Container Apps. Both were caused by the gap between “it runs” and “it is ready for production.”
Why this happens
Azure Container Apps offers Dapr as a built-in, managed integration. You enable Dapr per container app, define components at the environment level, and the sidecar shows up. There is no control plane to install and no Helm chart to maintain.
That convenience is exactly why teams skip the design work. On Kubernetes, the friction of installing Dapr forces conversations about namespaces, secrets, and upgrades. On ACA, you can reach a working demo before anyone asks who is allowed to use which component, what happens to in-flight work during a revision swap, or where workflow history is actually stored.
The defaults are tuned to get you started, not to be a production design.
Why common workarounds fall short
When the first incidents arrive, teams usually reach for quick fixes:
- Moving the connection string to an environment variable. The secret is still a static credential, still copied around, and still needs rotation.
- Adding retries in application code. Each service ends up with its own retry loop, its own timeout values, and no shared view of what “failing” means.
- Pinning to a single replica to avoid lost work. This hides the durability problem instead of solving it, and it gives up the scaling you chose ACA for.
- Treating the pilot environment as production. One environment, one set of components, and every change is a live experiment.
Each patches a symptom without changing how the system behaves when a replica disappears or an auditor asks who can read the state store.
The general approach
Production readiness for Dapr on ACA comes down to a few vendor-neutral principles:
- Least privilege for components. A component should be visible only to the apps that need it.
- No static secrets in configuration. Use workload identity where possible and a secret store where not.
- Declared, shared failure behavior. Timeouts, retries, and circuit breakers belong in policy, not scattered through code.
- Durable state for anything long-running. If work must survive a restart, its state must live somewhere that survives a restart.
- End-to-end visibility. A trace should follow a request across service calls and message hops.
- Separated environments and deliberate upgrades. Dev, test, and prod are different blast radii, and runtime versions change underneath you.
None of this is Azure-specific. ACA simply makes it easy to forget.
How to implement it on ACA
Scope every component
Dapr components support a scopes list that restricts which app IDs can load them. Without it, any Dapr-enabled app in the environment can use the component. Here is a generic Dapr component showing scopes and identity-based auth instead of a connection string:
apiVersion: dapr.io/v1alpha1
kind: Component
metadata:
name: orders-pubsub
spec:
type: pubsub.azure.servicebus.topics
version: v1
metadata:
– name: namespaceName
value: “orders-prod.servicebus.windows.net”
– name: azureClientId
value: “<user-assigned-identity-client-id>”
scopes:
– order-api
– fulfillment-worker
Field names differ by component type, so confirm them against the component reference before copying this pattern. ACA also has its own schema for defining environment-level components, so translate accordingly.
Replace connection strings with identity
Wherever a component supports Microsoft Entra authentication, use a managed identity and grant it the narrowest role it needs. Where a component still requires a secret, reference it from a secret store rather than inlining it. Then add a check in your pipeline that fails the build if a component file contains anything that looks like a key or connection string. The security review in the opening scene should have been a failed pull request, not a finding.
Define resiliency policies
Dapr resiliency policies (a kind: Resiliency resource) let you declare timeouts, retries with constant or exponential backoff, and circuit breakers, and apply them to apps, components, and actors. Start with the dependencies that hurt most: the broker, the state store, and any slow downstream service. Check the current ACA documentation for how resiliency is configured and which policy targets are supported in the managed integration.
Choose durable state stores for workflows
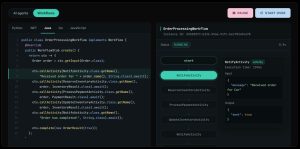
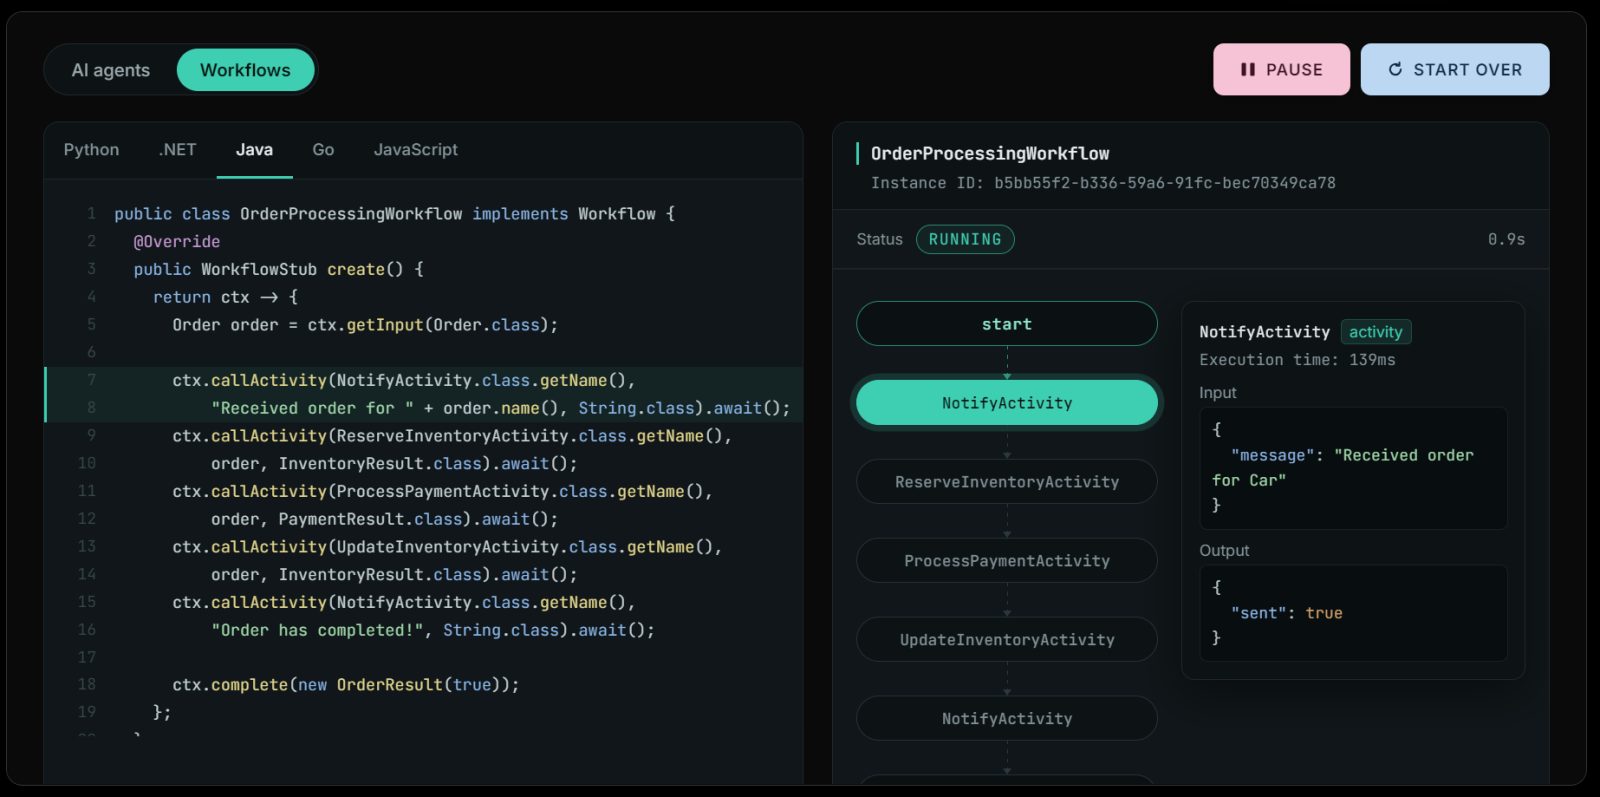
Dapr Workflow stores event-sourced history in a state store. After a crash, the workflow replays that history and completed activities are not re-executed. That guarantee is only as good as the store underneath it. An in-memory or ephemeral cache is fine for a demo and wrong for anything you care about.
Pick a durable, managed store such as Azure Cosmos DB or Azure Database for PostgreSQL, and back it up like any other system of record. Remember that orchestrator code must be deterministic, with all I/O in activities, or replay will produce surprises.
Wire tracing into Azure Monitor
Dapr emits OpenTelemetry traces and propagates W3C trace context across service invocation and pub/sub, and every sidecar exposes Prometheus metrics. Route traces to Application Insights or another Azure Monitor destination so you can follow a single order from API call to message to state write.
Separate environments and plan upgrades
Give dev, test, and prod their own ACA environments, with components and identities defined per environment in infrastructure as code. Promote component and policy changes the same way you promote application code.
Because Dapr is managed for you, the runtime version is not entirely on your schedule. Track which Dapr version each environment runs, read release notes before they reach prod, and keep your SDK versions aligned. Check the current ACA documentation for which Dapr features and versions are supported, rather than assuming parity with open-source Dapr on Kubernetes.
Version your workflows
Long-running workflows will outlive the code that started them. Dapr Workflow supports versioning, so plan how a new orchestrator version coexists with instances that started on the old one.
When managed Dapr is enough, and when it is not
For many teams, ACA’s managed Dapr integration is the right home: stateless services, pub/sub fan-out, modest workflows, and a platform team that prefers not to run a control plane.
The calculation changes when you need control over runtime versions and upgrade timing, Dapr features the managed integration may not expose, multi-cloud or on-premises deployment, or durable execution for AI agents that run for hours and must survive failures without repeating expensive LLM or tool calls. At that point, teams often look at running open-source Dapr on AKS, where they own the control plane, or at a managed platform built on Dapr.
Diagrid is one option in that second category. Its Catalyst product is positioned as a platform for durable workflows and agents, with deployment choices that include Diagrid-hosted, bring-your-own-cloud, and self-hosted. Whatever you evaluate, run your own failure tests against it rather than relying on any vendor’s description.
Production readiness checklist
Walk through this list with your platform and security teams before the next go-live:
- ☐ Every Dapr component has a scopes list naming only the app IDs that need it.
- ☐ No component contains a connection string or key; managed identity or a secret store reference is used instead.
- ☐ Resiliency policies cover the broker, the state store, and critical downstream services.
- ☐ Workflow state lives in a durable, backed-up store such as Cosmos DB or PostgreSQL.
- ☐ Pub/sub subscribers are idempotent and have dead-letter topics configured.
- ☐ OpenTelemetry traces reach Application Insights and can be followed across services.
- ☐ Dev, test, and prod are separate ACA environments defined in infrastructure as code.
- ☐ A load test has run against a revision update during peak-like traffic.
- ☐ Scale-to-zero behavior has been tested with long-running workflows in flight.
- ☐ A chaos test has killed replicas mid-workflow and confirmed resumption from history.
- ☐ Current Dapr version per environment is tracked, and someone owns reading release notes.
- ☐ A workflow versioning plan exists for changes to orchestration logic.
- ☐ A documented decision states why managed Dapr on ACA is sufficient, or what would trigger a move.
The revision-update and scale-to-zero tests matter most. They reproduce the opening scene on purpose, somewhere losing work is acceptable. If an in-flight order survives a revision swap in test, you have real evidence. If it does not, you found the problem before your customers did.
Conclusion
Dapr on Azure Container Apps removes a lot of operational weight, which is a real benefit. It does not remove the need for production design. Scope components, drop static secrets, declare resiliency, put workflow history in a store that survives restarts, trace everything, and treat upgrades as a planned event.
If your requirements grow toward long-running agents, strict upgrade control, or deployment outside a single cloud, compare AKS with a durable workflow platform built on Dapr, and test each against the same failure scenarios. The pilot that dropped orders during a busy hour is a common story. It does not have to be yours.